1. Wavelength Point Selection
All classes that extend the auswahl.PointSelector can be used to perform wavelength point selection,
i.e. the independent selection of informative wavelengths without taking spatial information into account.
Note that neither the number of features to select nor the hyperparameters of the different models are optimized
according to your use-case.
Use the methods available in sklearn.model_selection to determine a suitable set of parameters.
1.1. Variable Importance in Projection
Calculating the Variable Importance in Projection (VIP) is possible by using the VIP selection method.
This method uses the coefficients of a fitted Partial Least Squares (PLS) model to calculate the importance of each
wavelength (=variable). To calculate the VIPs, the X-score matrix T, the y-loading vector q and the normalized X-weight
matrix W are used. They are defined as:

where N is the number of samples, M is the number of features and K is the number of latent variables. The VIPs are computed by:
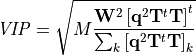
Note that the above equation uses a 1-dimensional target vector.
Examples:
VIP - Basic example: A VIP example usage for a synthetic regression task
VIP - Selection with a threshold: A VIP example that examines the calculated VIP scores to determine the number of features to select
References:
Stefania Favilla, Caterina Durante, Mario Li Vigni, Marina Cocchi, ‘Assessing feature relevance in NPLS models by VIP’, Chemometrics and Intelligent Laboratory Systems, 129, 76–86, 2013.
1.2. Monte-Carlo Uninformative Variable Elimination
Monte-Carlo Uninformative Variable Elimination (MC-UVE) uses random sampling to determine the stability of features.
Performing MC-UVE is possible by using the MCUVE selection method.
The method generates a large number of random subsets of the training data and fits a PLS model to each subset.
Afterwards, the importance of each feature is determined by computing the stability of the PLS’ regression coefficients.
If μ and σ are the mean and standard deviation of the regression coefficients,
the stability for the i-th feature is defined as:

The features with the highest absolute stability values are selected.
Examples:
MC-UVE - Basic example: An MC-UVE example usage for a synthetic regression task
References:
Wensheng Cai, Yankun Li and Xueguang Shao, ‘A variable selection method based on uninformative variable elimination for multivariate calibration of near-infrared spectra’, Chemometrics and Intelligent Laboratory Systems, 90, 188-194, 2008.
1.3. Random Frog
Random Frog (RF) is an iterative selection method that starts with randomly selected features which are adapted during the iteration process. Each iteration, a random sub- or superset is created and compared against the previously selected features by cross-validation. The RF method keeps track of a counter for each feature and the counters for all features in the “winning” set (i.e. higher cv score) are increased after each iteration. After performing all iterations, the features with the highest selection frequencies are selected.
RF is available in RandomFrog.
Examples:
Random Frog - Basic example: An RF example usage for a synthetic regression task
References:
Hong-Dong Li and Qing-Song Xu and Yi-Zeng Liang, ‘Random frog: An efficient reversible jump Markov Chain Monte Carlo-like approach for variable selection with applications to gene selection and disease classification’, Analytica Chimica Acta, 740, 20-26, 2012
1.4. Competitive Adaptive Reweighted Sampling
Competitive Adaptive Reweighted Sampling (CARS) is available in CARS.
CARS is an iterative algorithm, producing a candidate feature set with monotonly decreasing size in each iteration.
For Auswahl, the algorithm has been adapted to the use case of producing feature sets of a pre-specified size, by modifying
the shrinkage approach to eventually produce a set of the requested size.
The space of appropriately sized sets is explored through repeated runs of the CARS algorithm, exploiting the
competitive sampling of the algorithm:
The CARS algorithm combines a competitive sampling of features with a scheduled shrinkage of the number of features selected:
CARS considers an EDF (Exponential Decreasing function) to produce the upper bounds of features selected for the candidate set in each iteration. The importance of features is quantified using their absolute regression weights in a fitted Partial Least Squares (PLS) model. The importance is subsequently used as fitness in a competitive sampling procedure, in which the set of features is generated through sampling with replacement. The number of samples drawn is determined by the EDF.
Examples:
CARS - Basic example: A CARS example usage for a synthetic regression task
References:
Hongdong Li,Yizeng Liang, Qingsong Xu and Dongsheng Cao, ‘Key wavelengths screening using competitive adaptive reweighted sampling method for multivariate calibration’, Analytica Chimica Acta, 648, 77-84, 2009
1.5. Successive Projection Algorithm
Successive Projection Algorithm (SPA) is available in SPA.
The SPA algorithm addresses the frequent problem of high collinearity in spectroscopic data:
If N is the number of samples and M the number of features, the algorithm considers the features as M points in an N-dimensional vector space and conducts an iterative selection, by choosing the features with minimal lengths of projections onto the so far selected features. As a result, SPA constructs sets with minimum collinearity. Note, that SPA can only meaningfully construct sets of at most N features, which is the upper bound of linearly independent features.
The iterative scheme of the algorithm makes the initially selected variable a degree of freedom. Therefore, SPA considers every variable as candidate seed and subsequently selects the variable set with a maximum CV performance.
Note also, that the features are selected solely with regard to their collinearity. The quality w.r.t. the target quantity regression is only considered during the CV optimization of the initial variable.
Examples:
SPA - Basic example: A SPA example usage for a synthetic regression task
References:
Mário César Ugulino Araújo,Teresa Cristina Bezerra Saldanha, Roberto Kawakami Harrop Galvao, Takashi Yoneyama, Henrique Caldas Chame and Valeria Visani, ‘The successive projections algorithm for variable selection in spectroscopic multicomponent analysis’, Chemometrics and Intelligent Laboratory Systems, 57, 65-73, 2001
1.6. Variable Iterative Subspace Shrinkage Approach
The Variable Iterative Subspace Shrinkage Approach (VISSA) is an algorithm exploring the space of feature subsets
via a Weighted Block Matrix Sampling strategy and is available in VISSA
The algorithm creates a number of submodels in each iterations, consisting of random selections of variables under the restriction, that the number of submodels a variable participates in, corresponds to the weight of the variable calculated in the preceding iteration. The weight of a variable is calculated by the share of models the variable appears in, among the best 5% of submodels tested with Cross Validation. If variables appear in non or all of these top submodels, the search space is effectively shrunken.
The algorithm terminates, if either the required number of variables have achieved a weight of circa 1, or the variable weights in an iteration produce a deteriorating average Cross Validation score of the top submodels compared to the previous iterations.
Examples:
VISSA - Basic example: A VISSA example usage for a synthetic regression task
References:
Bai-chuan Deng, Yong-huan Yun, Yi-zeng Liang, Lun-shao Yi, ‘A novel variable selection approach that iteratively optimizes variable space using weighted binary matrix sampling’, Analyst, 139, 4836–-4845, 2014.